Just a few days before public deployment of my new website this error popped up in the terminal. Apache was running fine but my favorite php test server crashed after 5 minutes. Continue reading PHP Segmentation Error 11
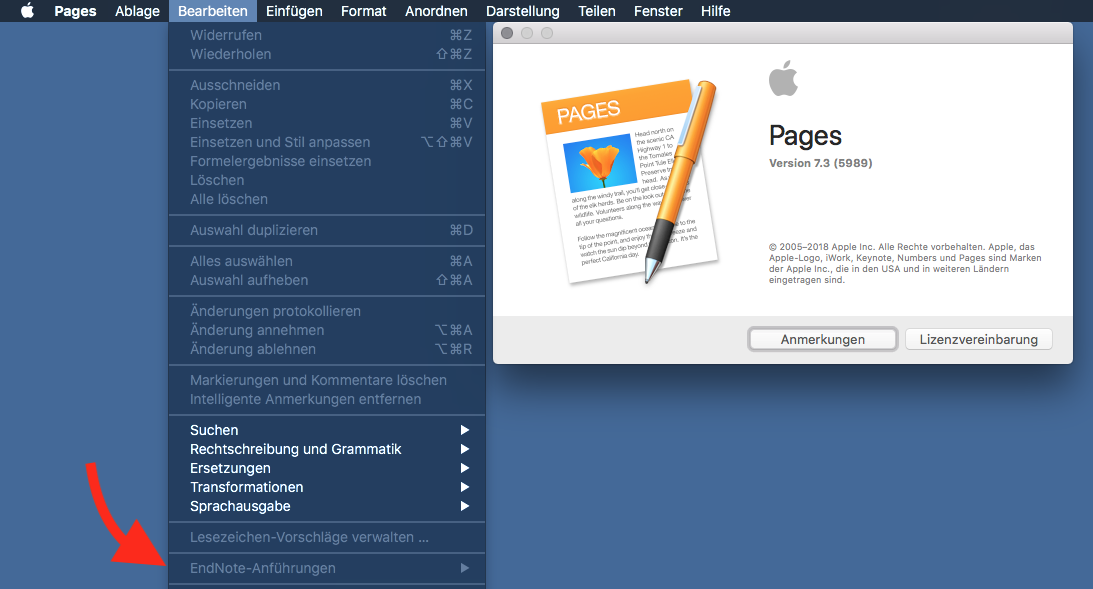
Just found a plugin from Apple that allows Endnote citations in Pages. So Apple is also interested in the science industry :-)
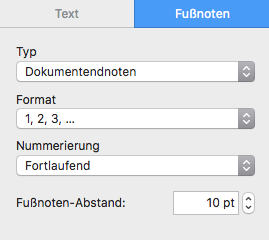
Just in case you arrive here from Google by trying to reformat footnotes as endnotes. Your cursor needs to be on an existing footnote, only then the formatting menu appears top right.
Found at https://www.nature.com/articles/ncpuro0294#article-info via https://twitter.com/MaartenvSmeden/status/1071138625415458817
A mistake in the operating room can threaten the life of one patient; a mistake in statistical analysis or interpretation can lead to hundreds of early deaths. So it is perhaps odd that, while we allow a doctor to conduct surgery only after years of training, we give SPSS® (SPSS, Chicago, IL) to almost anyone. Moreover, whilst only a surgeon would comment on surgical technique, it seems that anybody, regardless of statistical training, feels confident about commenting on statis- tical data. If we are to bring the vast efforts of research to fruition, and truly practice evidence- based medicine, we must learn to interpret the results of randomized trials appropriately.
After digging around in the console, I found some mixed content types – maybe the developers did not work on a https enabled site?
The only solution right now is the “Classic Editor” plugin.
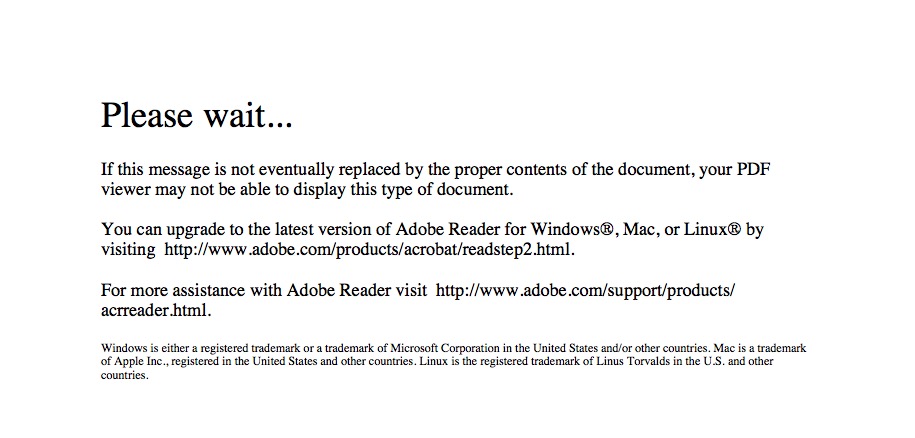
I dont’t understand why the ICMJE Conflicts of Interest of the Vancouver group is NOT distributed as a standard PDF but as an Adobe Form that can be opened only after installing a lot of unnecessary software that opens a lot of unnesssary ports transmitting a lot of unnecessary data. This is how it looks natively on a Mac
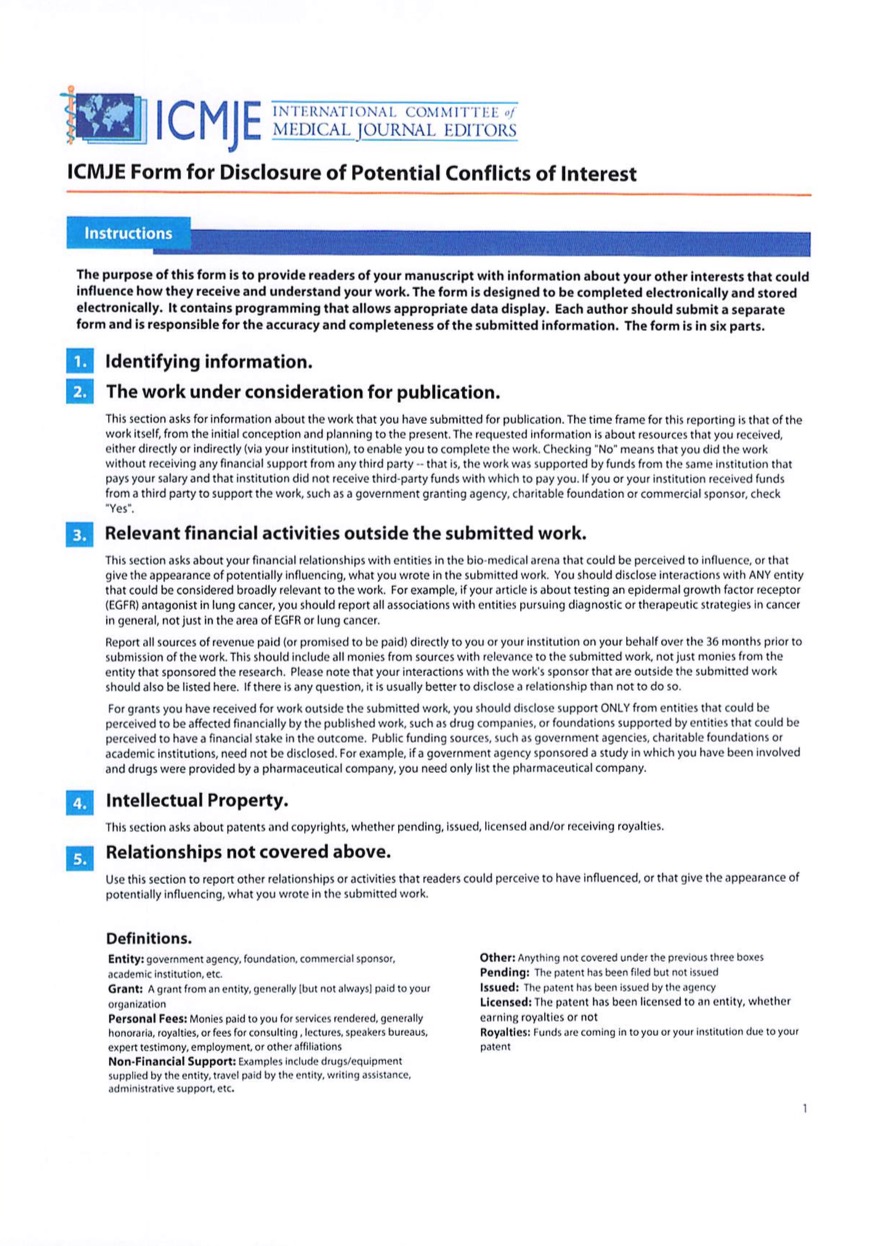
and this is how it should look like
Adobe Acrobat Reader DC does not even allow printing into a PDF, clearly spyware behavior forcing data collection on an unknown destination.
While working on the revision of a paper on GDPR & open access, I found an interesting table who is fighting whom in science.
| Country | Consortia | Dispute |
|---|---|---|
| The Netherlands | VSNU | Royal Society of Chemistry |
| Germany | Deal | Elsevier |
| Sweden | Bibsam | Elsevier |
| France | Couperin | Springer Nature |
Do we need any of these publishers? I would say no.
What’s currently allowed is in the Sherpa/Romeo list.
This short script is quite useful for DSGVO complaint, aeh compliant websites. Just put a grey picture in /images/externalcontent.png or wherever you want

and insert a short script in the wordpress header.
function showyou() {
$('iframe[name*=".com"]').each(function(e) {
var src=$(this).attr('name');
$(this).attr('src',src);
$(this).show();
});
}
$(document).ready(function(){
$('iframe[src*=".com"]').each(function(e) {
var src=$(this).attr('src');
$(this).attr('name',src );
$(this).attr('src','');
$(this).after('<img class="me" src="/images/externalcontent.png" onclick="$(\'.me\').hide();showyou();"/>
');
$(this).hide();
});
});
by
Das Stuttgarter Messprojekt ist ausführlich auf https://luftdaten.info/ erklärt, die Feinstaub Theorie auf ruhrmobil-e.de/.
Dahinter steckt der Laser Staub Sensor SDS011.
Nova Fitness SDS011 is a professional laser dust sensor. Fan mounted on sensor automatically sucks air. Sensor uses laser light scattering principle to measure value of dust particles suspended in the air. Sensor provides high precision and reliable readings of PM2.5 and PM10 values. Any change in environment can be observed almost instantaneously – short respond time below 10 seconds. Sensor in standard mode reports reading with 1 second interval.
Measured values: PM2.5, PM10
Range: 0 – 999.9 μg /m³
Resolution: 0.3μg/m3
Work environment:-10 ~ +50°C
Counting yield: 70%@0.3μm, 98%@0.5μm
Relative error: Maximum of ± 15%, ±10μg/m3 25°C, 50%RH
Cycle: 1004ms±1%
Service life: up to 8000 hours
according http://www.segor.de/dokumente/sds011_pm2.5_v1.3.pdf
Mit 70mA Stromverbrauch kann der Sensor damit auch mobil mit einer gängigen Powerbank (zB 3.500 mAh) 50 Stunden lang betrieben werden, am besten parallel zu einem alten Mobilfunkgerät, das nicht nur einen GPS Track aufzeichnet, sondern auch per Wifi gleich die Daten speichert. Mehr zur Evaluation des Sensors auf luftdaten.info bzw lubw.baden-wuerttemberg.de Zusammengefasst
* zufriedenstellende Korrelation an Tagen mit mittlerer Luftfeuchtigkeit (50 – 70 % r. F.) und Konzentrationen kleiner 20 μg/m3
* deutliche Abweichungen bei Schwankungen der klimatischen Bedingungen (Luftfeuchte, Luftdruck, Lufttemperatur)
* Sensoren aus unterschiedlichen Chargen weisen unterschiedliche Messergebnisse auf
* undefinierter Probengasstrom durch ungeregelten Lüfter führt zu starken Schwankungen des Messvolumens
There is a new clinical trial D3ForMe that has a big benefit in my eyes: Avoiding the high local vitamin D in the gut Peyers’ Patch after oral supplementation.
Oral supplementation likely affects gut-specific homing leading activated T cells and antibody-secreting cells (ASCs) to both inflamed and non-inflamed regions of the gut. Also antigen recognition may be affected by inhibited DC maturation.
In an earlier vitamin D3 could be safely be delivered through the dermal route.
Es gibt in Deutschland immer noch viele Kammer-, Sozial- und Vorstandswahlen, die aus angeblichen Fairnessgründen die Kandidatenliste alphabetisch reihen. Dabei wissen die meisten Organisationen nicht, wie sie sich damit vor allem selbst, aber auch den Kandidaten schaden.
Wahlen von Kandidatenlisten in alphabetischer Reihenfolge sind nämlich vor allem dann ein Problem, wenn A. die Wähler die Kandidaten nicht kennen, es B. einen großen Überhang von Kandidaten im Verhältnis zu den Gewählten gibt, C. die Reihung als Empfehlung missverstanden wird und D. die Wahlergebnisse relativ nahe beieinander liegen.
In der englischen Literatur ist das alles als “Ballot Order Effect” bekannt und kann auf vielen Blogs nachgelesen werden:
https://daily.jstor.org/ballot-position/
https://www.pulj.org/the-roundtable/avoiding-election-bias
https://www.bbc.com/news/blogs-magazine-monitor-27426319
https://www.cbc.ca/news/politics/grenier-ballot-order-1.4608059
http://www.centerforpolitics.org/newslet_909cb.html
Der Effekt ist enorm, mit einem Buchstaben im vorderen Drittel liegt die Wahlchance bei ca 65%, im mittleren Drittel bei 25%, im letzten Drittel bei 10%. Am Ende der Liste zu stehen ist besonders schlecht, auch bekannt als “voter fatigue” (das ändert sich allerdings wenn die Liste sehr lange ist, dann wird man wieder etwas häufiger gewählt).
Das folgende Beispiel illustriert an einem praktischen Beispiel, wie eine Liste von 20 Kandidaten am besten unter den Wählern verteilt wird, um den “Ballot Order Effect” zu vermeiden.
l <- LETTERS[1:20]
l
[1] "A" "B" "C" "D" "E" "F" "G" "H" "I" "J" "K" "L" "M" "N" "O" "P" "Q" "R" "S" "T"
# Zuerst wird die alphabetische Reihenfolge aufgelöst
l <- sample(l)
l
[1] "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D"
# Dann wird der jeweils letzte Namen nach vorne gerückt
r <- NULL
for (v in l[20:1]) {
x <- c( l[grep(v,l):20], l[1:(grep(v,l)-1)] )[1:20]
r <- rbind (r,x)
}
r
# Jede Zeile gibt nun einen von 20 Wahlvorschlägen aus
[,1] [,2] [,3] [,4] [,5] [,6] [,7] [,8] [,9] [,10] [,11] [,12] [,13] [,14] [,15] [,16] [,17] [,18] [,19] [,20]
x "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E"
x "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A"
x "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R"
x "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S"
x "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N"
x "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P"
x "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O"
x "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H"
x "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G"
x "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I"
x "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T" "B"
x "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J" "T"
x "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M" "J"
x "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M"
x "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L"
x "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F"
x "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K"
x "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C"
x "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q"
x "Q" "C" "K" "F" "L" "M" "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D"
# Diese 20 Wahlvorschläge werden nun in gleicher Stückzahl ausgedruckt und verteilt
# Bei online Wahlen lässt man einen Counter mitlaufen oder noch einfacher, man wirft
# alle 3 Sekunden den nächsten Vorschlag aus
r[ floor(as.numeric(format(Sys.time(), "%S"))/3), ]
[1] "J" "T" "B" "I" "G" "H" "O" "P" "N" "S" "R" "A" "E" "D" "Q" "C" "K" "F" "L" "M"
Es sollte also nicht all zu schwer sein, faire Wahlen durchzuführen.
technology review explains a new breed
all this has given rise to a new breed: the Depressed Former Internet Optimist (DFIO). Everything from public apologies by figures in the technology industry to informal chatter in conference hallways suggests it's become very hard to find an internet Optimist in the old, classic vein. There are now only Optimists-in-retreat, Optimists-in-doubt, or Optimists-hedging-their-bets.
and continues
Many Optimists believed that the structure of the internet by itself-manifested in collaborative projects such as wikis or crowdfunding-would bend social outcomes in their favor. One response to the events of 2016 has been to revisit this assumption, claiming that while the basics might have been right, more work is needed to realize the original vision.
So may I add here an advertisement of Tim Berner-Lee’s Solid project operating Inrupt?
Imagine if all your current apps talked to each other, collaborating and conceiving ways to enrich and streamline your personal life and business objectives? That's the kind of innovation, intelligence and creativity Solid apps will generate.
As we are now redefining content why not also getting paid by Brave when browsing? The not not evil Alphabet company has already announced some major changes.
Geoffrey R. Loftus in Behavior Research Methods, Instruments, & Computers 1993, 25 (2), 25() 256
Hypothesis testing, while by far the most common statistical technique for generating conclusions from data, is nonetheless not very informative. It emphasizes a banal and confusing question ("Is it true that some set of population means are not all identical to one another?") whose answer is, in a mathematical sense, almost inevitably known ("No"). Hypothesis testing, as it is customarily implemented, ignores two issues that are generally much more interesting, important, and relevant: What is thepattern of population means over conditions, and what are the magnitudes of various variability measures (e.g., standard errors of the mean, estimates of population standard deviations)?
so auch in G. Lind “Effektstärken: Statistische, praktische und theoretische Bedeutsamkeit empirischer Befunde”, Privatdruck 2012
Was aber selten (viel zu selten!) in Erwägung gezogen wird, ist die Möglichkeit, Befunde auf ihre theoretische, inhaltliche Bedeut- samkeit hin zu untersuchen: Welche Wertedifferenz ist für unser subjektives Empfinden und unsere Handlungen bedeutsam? Ab welcher Effektstärke können wir davon sprechen, dass eine Therapie- methode oder eine pädagogische Intervention wirklich etwas bringen und den Aufwand lohnen, den alle Beteiligten investieren müssen? Tritt der Effekt immer oder nur unter bestimmten Bedingungen auf? Ist er an Besonderheiten der Studie (Umfang des Samples, Streuung der unabhängigen Variablen) gebunden? Passt der Effekt zu dem, was wir bereits über die Variablen wissen, die wir untersuchen, oder stellt er fundiert geglaubte Theorien in Frage?
Congress report Annual AGD Meeting 2018, Potsdam Oct. 5-6
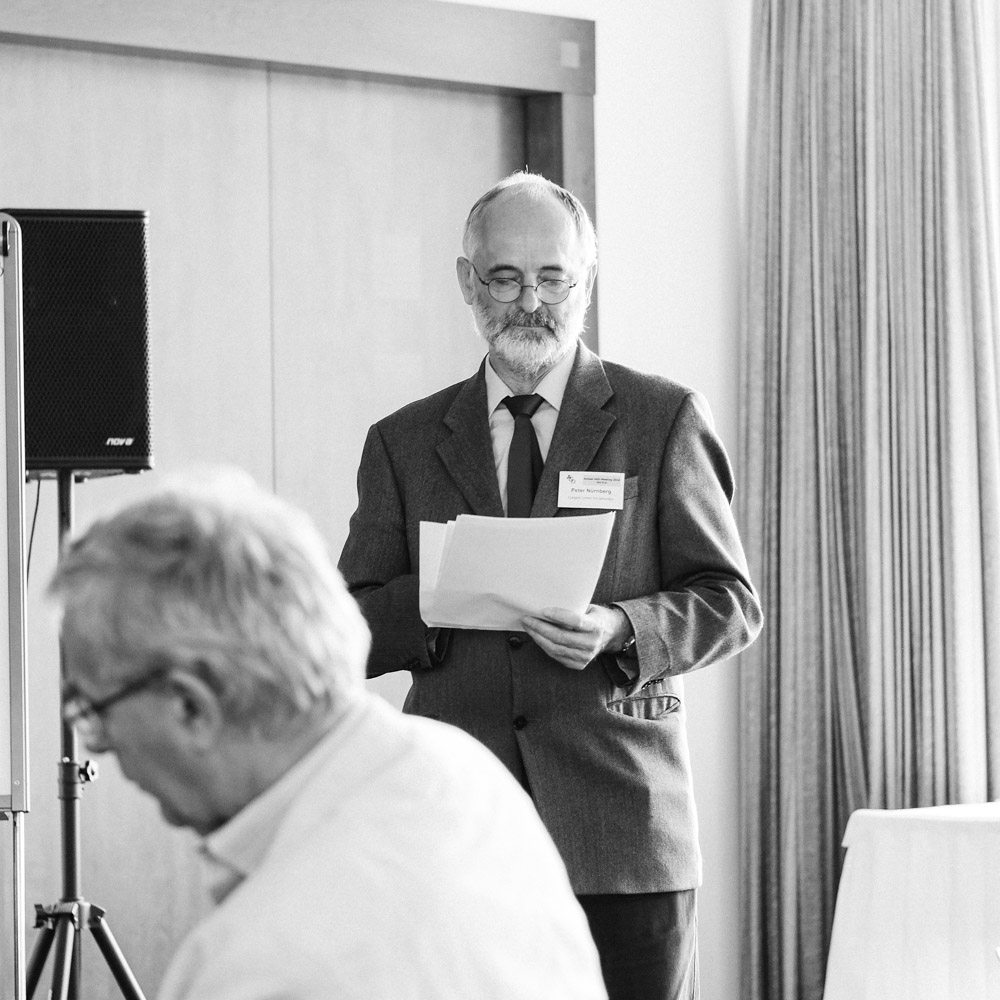
Welcome and Opening of Symposium by Peter Nürnberg, President of the AGD and Joachim L. Schultze, Chair of the Program Committee.
The AGD meeting was interesting and a great primer for all of us who are not directly working with single cells.
Maybe it is an unusual research field – dissecting single cells in the first stage is not a trivial task. And single cell means single cell experiment that can be replicated only in other cells. The current readout is RNA content at a given time while genomics and proteomics still need to be integrated. Experiments cover mainly abundant RNAs and for cost reasons only the 3′ ends. The statistical analysis usually is a 2 dimensional PCA (known to overfit noise) so this not a trivial approach at all. Newly identified cell cluster need careful confirmation as addressed in the talk of Andreas Schlitzer.
Continue reading New insights by single-cell genomics
http://www.philzimmermann.com/EN/essays/WhyIWrotePGP.html
Throughout the 1990s, I figured that if we want to resist this unsettling trend in the government to outlaw cryptography, one measure we can apply is to use cryptography as much as we can now while it’s still legal. When use of strong cryptography becomes popular, it’s harder for the government to criminalize it. Therefore, using PGP is good for preserving democracy. If privacy is outlawed, only outlaws will have privacy.